Notes on the
LLM economy.
Curated insights, tutorials, and field notes on model routing, prompt caching, agent cost, and shipping AI products that don't lock you in.
Trending
Seedream 5.0 Pro on Mesh API: Ad Creative, Brand Kits & UI
Seedream 5.0 Pro is live on Mesh API at $0.11/image. It generates legible ad creative, brand kits, and UI mockups from one API call. Five use cases, tested.
Your Model Eval Framework Is Broken. Claude Detects Prefilled Prompts and Silently Resists.
Claude Opus 4.5 detects tampered prefilled responses with 67.6% accuracy—and doesn't tell you. Here's why your eval harness is confounded, and how to fix it.
Google's Open Knowledge Format Is Smart. But Here's What's Missing.
Google's Open Knowledge Format (OKF v0.1) formalizes how AI agents consume organizational knowledge. But empirical performance gains, governance, and migration strategies are still undefined. Here's what the first 100 deployments will cost.
Recent posts
Seedance 2.5 1080p: Real Render, 25% Cheaper
Seedance 2.5 native 1080p is live at $8.77 per 1M tokens, 25% below going direct. We read the token meter to prove it renders natively instead of upscaling.
Seedream 5.0 Pro on Mesh API: Ad Creative, Brand Kits & UI
Seedream 5.0 Pro is live on Mesh API at $0.11/image. It generates legible ad creative, brand kits, and UI mockups from one API call. Five use cases, tested.
Your Model Eval Framework Is Broken. Claude Detects Prefilled Prompts and Silently Resists.
Claude Opus 4.5 detects tampered prefilled responses with 67.6% accuracy—and doesn't tell you. Here's why your eval harness is confounded, and how to fix it.
Google's Open Knowledge Format Is Smart. But Here's What's Missing.
Google's Open Knowledge Format (OKF v0.1) formalizes how AI agents consume organizational knowledge. But empirical performance gains, governance, and migration strategies are still undefined. Here's what the first 100 deployments will cost.
Why 4B Models Beat 671B Giants at Theorem Proving. (It's Not What You Think.)
A 4B model beats a 671B giant at theorem proving—but it's training, not parameters. Benchmark breakdown, compute-parity gap, and practitioner guide.
Google Analytics Now Tracks ChatGPT, Claude, and Gemini Traffic Separately. Here's What Your Real Metrics Look Like.
GA4's new 'AI Assistant' channel separates ChatGPT, Claude, and Gemini traffic automatically—no setup needed. But referrer-based measurement means 40-70% of AI sessions still hide in Direct. Here's the full picture.
AI Agents Fail Real Workflows at Scale. 1,000+ Long-Horizon Tasks Show the Production Gap.
Current AI agents solve well-specified labs (100% pass rates) but collapse on 1,000+ long-horizon real-world tasks (2–24% success). The gap between research benchmarks and production is orders of magnitude.
Stop Fine-Tuning Tool Workflows. Evolutionary Search Raises Small Models From 3% to 24%.
Evolutionary search lifts small-model feasibility 3%→24% without fine-tuning. What Evoflux measured, what it missed, and when fine-tuning wins.
60-80% of Agent Traffic Goes Local Now. Here's Why Single-Model Strategies Lost.
Agentic traffic grew 1,300% in 2025. Routing 60-80% to local LLMs cuts costs 40-85% at 90%+ accuracy. The 60-80% is a forecast. We mapped what's real.
LangChain and AutoGPT Have Zero Memory-Integrity Safety. One Poisoned Write Breaks 88.9% of Decisions.
Three major agent frameworks—LangChain, AutoGPT, and OpenAI Agents SDK—ship with zero memory-integrity safeguards. Here's what that costs you.
When Prompt Caching Actually Breaks Even: We Mapped the Latency vs Cost ROI
Prompt caching claims 90% savings, but break-even depends on hit rate, prefix size, and provider. We mapped the exact ROI frontier—including the scenarios where caching hurts.
Why Your LLM Provider's Generous Daily Quota Is a Lie (And What the Real Bottleneck Actually Is)
Developers think they have millions of tokens/day. In practice, tokens-per-minute limits and concurrency caps constrain you first. We mapped the bottleneck across 5 major providers.
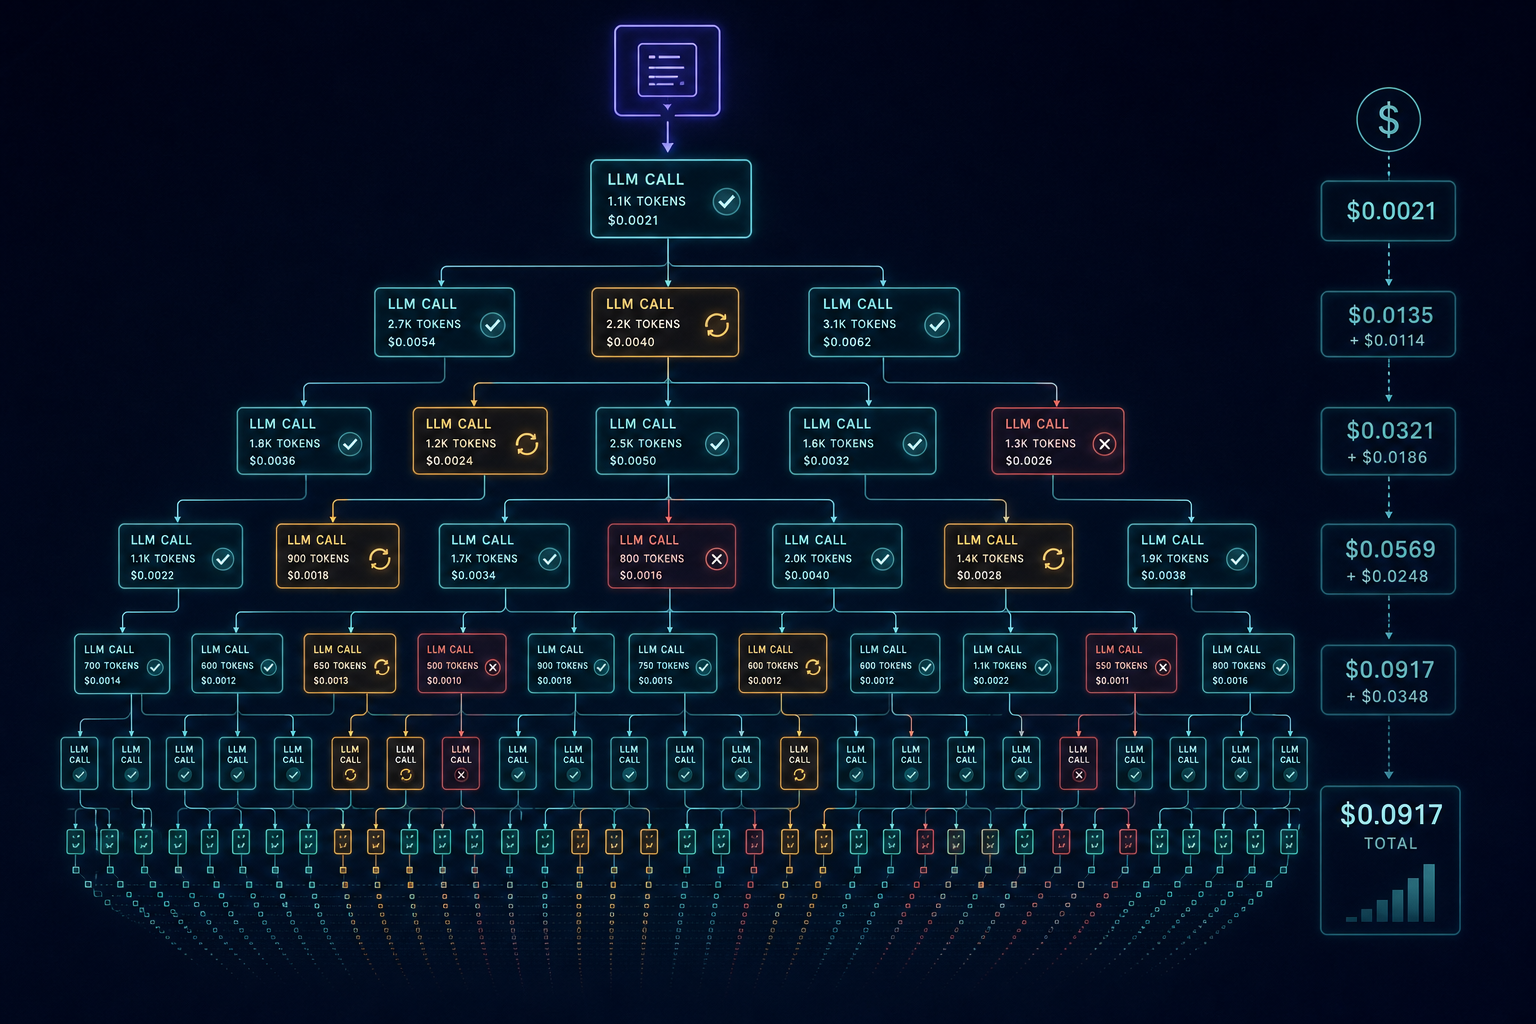
Your Agent Task Costs $0.50 in Tokens but $8 in Retries. Where Your LLM Bill Actually Goes.
Headline agent cost is prompt tokens. Real cost is retries, re-prompting on tool failures, and context replay. Learn to measure where your LLM bill actually goes.
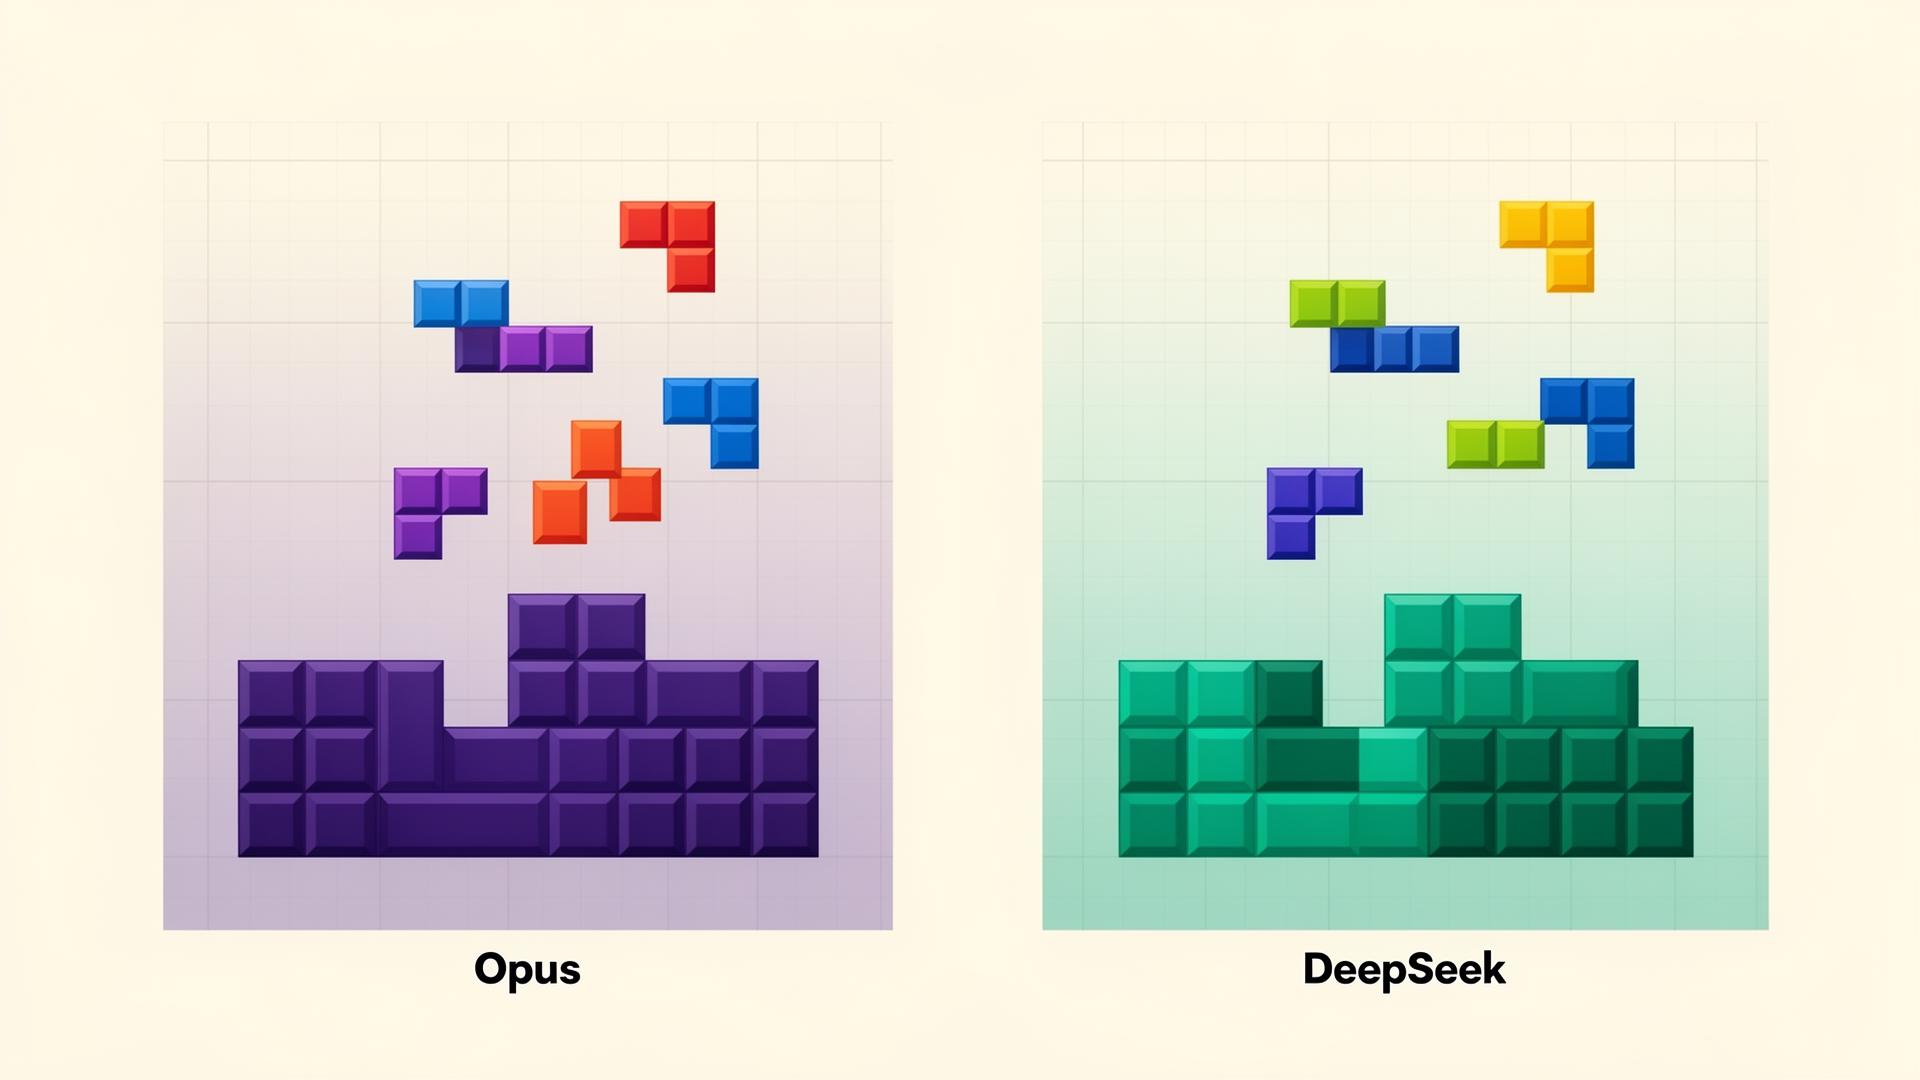
We Made Two LLMs Play Tetris. The Winner Wasn't the Better Player.
Claude Opus 4.8 vs DeepSeek V3.1 at turn-based Tetris, both served through Mesh API. Placement is basically solved, so the contest measures something more interesting: temperament.
Why Claude Design Burns Your Quota (and How to Fix It)
We spent a 5-hour quota plus $8 in one Claude Design prompt. Here is why code-based design costs so much, and the hybrid workflow that keeps it cheap.
Asia's largestsovereign AI gateway.
1,000+ AI models. One endpoint. Your data stays inside your border.