 Two paths for improving tool-calling agents: upfront fine-tuning versus inference-time evolutionary repair
TL;DR
- Evolutionary search over MCP-style tool workflows raises small-model execution feasibility from ~3% to 17–24%, without touching model weights (Evoflux, arXiv 2606.12674, 2026).
- Execution feasibility ≠ task success. A workflow that runs without syntax errors can still return the wrong answer — Evoflux doesn't measure correctness.
- SFT and SFT+DPO collapse below zero-shot on small training corpora: supervised approaches backfire when data is scarce.
- Fine-tuning still wins on structured, domain-specific tasks — fine-tuned SLMs beat carefully-prompted LLMs by ~10% on structured workflow generation (arXiv 2505.24189, 2025).
- The missing experiment: no published paper measures feasibility, answer quality, token cost, and robustness under tool drift simultaneously, across all approaches.
What the Evoflux Paper Actually Measured
The Evoflux paper (arXiv 2606.12674, 2026) tests a deceptively simple idea: instead of fine-tuning a small model to plan tool calls correctly, repair failing plans at inference time using evolutionary search.
The baseline is stark. Small planners — 3B–7B parameter language models — generate syntactically executable tool workflows only 3% of the time when prompted zero-shot on MCP-Bench, a benchmark of ~250 Model Context Protocol tools (Hugging Face paper card for Evoflux, 2026). Evolutionary repair changes that. The model generates a plan, watches it fail, feeds the failure signal back to itself, and regenerates. Repeat until a plan executes or you hit the retry limit. After a few repair cycles, execution feasibility climbs to 17–24%.
That's a 6–8× improvement without touching model weights.
There's also a counterintuitive result in the baseline comparisons. SFT and SFT+DPO — trained on mined teacher traces — often perform worse than zero-shot on small training corpora. The paper's framing: "under tight teacher-trace budgets, execution-grounded search transfers more reliably than weight updates" (Evoflux, arXiv 2606.12674, 2026). Data scarcity doesn't just limit the upside. It can push you below where you started.
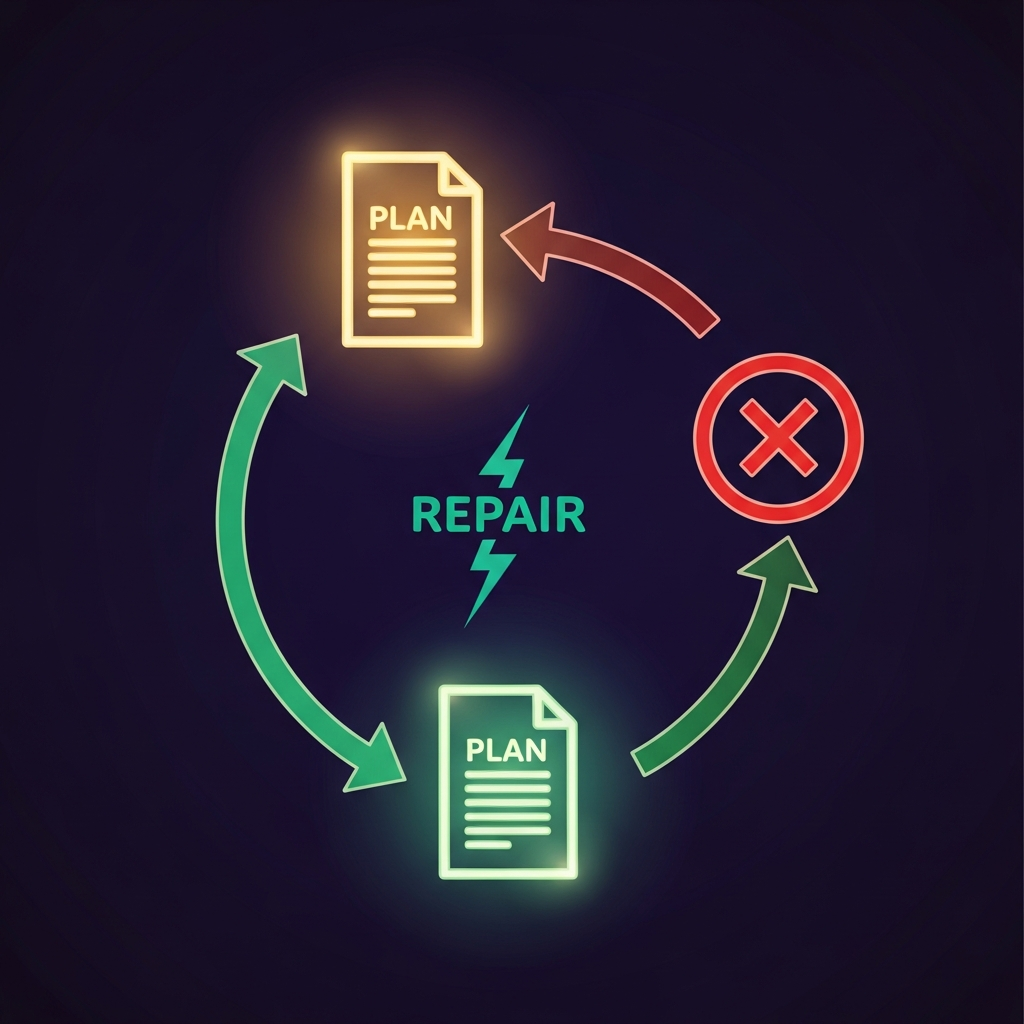 Evoflux's core loop: generate a plan, detect execution failure, repair at inference time, repeat
The Metric Gap: Feasibility Isn't Task Success
Here's the number buried beneath the headline: 24% execution feasibility means 24% of generated workflows ran without syntax errors. It says nothing about whether those workflows produced the right answer.
A workflow can be perfectly executable and still call tools in the wrong order, pass incorrect arguments, misinterpret a tool's return value, or aggregate results incorrectly. The output lands in the caller's lap, syntactically clean and semantically wrong.
Evoflux doesn't report task-success rate, answer quality, or F1 on actual user goals. It doesn't include human-judged correctness. The paper's own framing confirms this: "execution feasibility" is the metric, defined as whether a plan runs to completion. What happens after completion isn't in scope.
This isn't a minor caveat. For practitioners deciding whether to deploy a tool-calling agent, the question isn't "does the workflow run?" It's "does it give users the right answer?"
Contrast the Evoflux metric with the one used in "Fine-Tune an SLM or Prompt an LLM? The Case of Generating Low-Code Workflows" (arXiv 2505.24189, 2025): structured-output quality, measured against ground-truth JSON. That paper found fine-tuning an SLM improves output quality by ~10% on average versus carefully-crafted prompts on larger LLMs. On enterprise-specific features, the fine-tuned SLM outperformed GPT-4o.
These two papers aren't contradicting each other. They're measuring different things. Evoflux asks: "Does the workflow execute?" The SLM study asks: "Is the output correct?" Both questions matter. Neither paper answers both.
Evoflux moves workflows from the bottom row to the top row. It doesn't report whether they land in the left column (correct) or the right column (wrong).
The Cost Blind Spot
Evolutionary repair sounds cheap. It isn't necessarily. Each repair loop costs tokens: generate a plan, execute it, detect the failure, feed that signal back to the model, generate a revised plan. Repeat until a plan executes or the retry budget expires.
The Evoflux paper notes that ReAct carries "far higher variance and token cost" compared to zero-shot—but never quantifies it (arXiv 2606.12674, 2026). Evolutionary repair's own token overhead is similarly unmeasured.
The practical question: is the jump from 3% to 24% execution feasibility worth it if evolutionary search triples the token cost per task? We don't know. Evoflux doesn't report tokens-per-successful-task, wall-clock latency, or cost per correct result for any approach.
| Approach | Execution Feasibility | Tokens/Task | Latency | Cost/Successful Task |
|---|---|---|---|---|
| Zero-shot | ~3% | baseline | baseline | very high (low feasibility) |
| ReAct | high variance | "far higher" (unquantified) | high variance | unknown |
| Evoflux (evolutionary search) | 17–24% | ? | ? | ? |
| SFT/SFT+DPO (small corpus) | ≤3%, can collapse | baseline | baseline | very high (collapses) |
Source: Evoflux, arXiv 2606.12674, 2026. Token/latency/cost cells are gaps in the literature — not numbers from the paper.
Fine-tuning's cost structure is different but also underspecified. Upfront costs: data curation (the real bottleneck, per Fireworks AI's practitioner analysis, 2025), training compute, and evaluation. Per-inference cost: standard latency, no repair loops. But if the fine-tune collapses on small corpora—as Evoflux shows it can—the upfront cost bought worse-than-baseline performance.
Both approaches have cost blind spots. Any "search is cheaper than fine-tuning" claim is premature until someone measures tokens-per-successful-task on the same workload.
Robustness and Generalization
MCP-Bench is a snapshot: ~250 tools in a fixed configuration at evaluation time (Evoflux, arXiv 2606.12674, 2026). Real tool ecosystems don't sit still.
Tool schemas get versioned. APIs add required parameters. Old tools get deprecated; new ones appear. Intermittent failures spike and subside. Cross-domain generalization — financial APIs versus developer tools versus internal business systems — isn't tested anywhere in the Evoflux evaluation.
 Real tool ecosystems drift: schemas change, tools are added and removed, and reliability varies — neither approach has been benchmarked under realistic drift
For fine-tuned models, tool drift is a familiar problem. Overfit to a fixed schema and you get brittle agents that fail when a parameter is renamed. The cadence of retraining to stay current is unmeasured across the literature.
Evolutionary search has a structural advantage here: it can adapt at inference time. When a plan fails because the tool's schema changed, the repair loop generates a revised plan without weight updates. But this adaptation isn't free. The model must explore more of the search space if tool boundaries shift, burning tokens on invalid branches.
Neither approach has been benchmarked against realistic tool drift scenarios. MCP-Bench is a clean snapshot; production agents live in a stream of API changes. Teams building on either approach should expect to measure robustness themselves — the published results won't transfer cleanly to a changing tool ecosystem.
When Fine-Tuning Still Wins
The Evoflux result is real, but it's also specific. Execution feasibility on MCP-Bench is one metric in one setting. There are task types where fine-tuning holds a clear, measurable advantage.
The most direct evidence: "Fine-Tune an SLM or Prompt an LLM? The Case of Generating Low-Code Workflows" (arXiv 2505.24189, 2025) found fine-tuned SLMs improve quality by ~10% on average versus the best GPT-4-class prompts on structured JSON workflow generation. Fine-tuning changes behavior, not knowledge. It's a poor tool for keeping facts current, but it's strong at enforcing output format, maintaining structural constraints, and producing consistent results across millions of calls.
That consistency matters in specific situations:
- Output format is load-bearing — strict JSON, structured logs, SQL queries where a malformed response breaks a downstream system
- Task volume is high — the format-enforcement benefit compounds when the same narrow task runs thousands of times per day
- Schema is stable — if the tool set and expected output don't change, data curation is a one-time investment
- Behavior control matters more than adaptability — regulated or high-stakes settings where consistent, auditable behavior is required
Expert practitioners are consistent on this framing (Vectorize.io, 2025; CBTW, 2025): fine-tuning is rarely first — start with prompts, retrieval, and tools — but it remains the best last step for narrow, stable, repeated tasks at scale.
There's also a hybrid path that neither paper explores: use evolutionary search to generate high-quality execution trajectories, then fine-tune on the successful ones. Search provides the training data; fine-tuning locks in the behavior. Neither approach in isolation captures both benefits.
The Missing Experiments
Here's the honest state of the literature: nobody has published a single benchmark measuring execution feasibility, answer quality, tokens-per-successful-task, wall-clock latency, and robustness under tool drift — all at once, across zero-shot, ReAct, Evoflux evolutionary search, SFT, and SFT+DPO — under a shared compute and data budget.
That experiment doesn't exist yet (research gap synthesis, 2026).
What the field has instead are fragments. Evoflux is rigorous on execution feasibility and silent on everything else. The SLM fine-tuning study is rigorous on structured-output quality and doesn't test evolutionary repair. Practitioner literature is strong on heuristics and light on controlled measurements. The broader evolutionary optimization landscape — Cognify's hierarchical workflow autotuning, iEvoFlow's human-in-the-loop search — confirms that workflow-level optimization can beat weight-update approaches in their respective domains, but neither maps to tool-calling LLM agents with head-to-head cost data.
The specific gaps that matter most for practitioners:
- End-to-end task success rate — does a user get a correct answer, not just a workflow that ran?
- Tokens-per-successful-task across all approaches under the same retry budget
- Cross-domain robustness — does the 3%→24% improvement hold on financial APIs, or developer tools, or internal business systems?
- Behavior under tool drift — what happens when schemas change mid-deployment?
- Hybrid regimes — what does search-generated training data do for a fine-tuned model?
Until someone runs this comparison with shared infrastructure and published methodology, teams will keep making the choice on partial evidence. The absence of unified cost/quality data is the main reason the "fine-tuning is dead" versus "fine-tuning is still necessary" debate keeps cycling without resolution.
Practical Decision Framework
Stop asking "search or fine-tune?" Start asking "what's my constraint?"
Data scarce, tools change often: Use evolutionary search. Fine-tuning on small, heterogeneous corpora can collapse below zero-shot on MCP-style tasks (Evoflux, 2026). Search adapts at inference time without weight updates.
Data abundant, task is stable: Consider fine-tuning — particularly when structured output format is load-bearing. Fine-tuned SLMs improve quality ~10% on structured workflows versus prompted LLMs (arXiv 2505.24189, 2025). Run search first to generate high-quality trajectories, then fine-tune on the successful examples.
Somewhere in between (100–1,000 examples, moderate change rate): Start with search. Measure answer quality on your actual workload — not execution feasibility. If a quality gap remains after optimizing the search procedure, fine-tune on the examples where search succeeded.
Three things to stop assuming:
- "Fine-tuning is dead." It isn't. It's rarely first, but it remains the right final step for narrow, stable, high-volume tasks with consistent output requirements.
- "Evolutionary search is always cheaper." Token overhead from repair loops is unmeasured in the literature. Measure it on your specific workload before committing to the approach.
- "MCP-Bench results transfer to my tools." They don't. Your schema, your task distribution, and your quality bar are different. The 3%→24% improvement may be larger or smaller on your workload.
The discipline that actually resolves this: pick one metric that maps to business value — task success rate, cost per correct answer, human override rate — and run the comparison on your own workload. That's slower than reading a paper. It's also the only way to actually know which approach fits your constraint.
If you need to test multiple optimization approaches on the same model across providers without managing separate API contracts, Mesh API's compare endpoint routes the same prompt to multiple models and returns structured side-by-side results — which makes the before/after measurement significantly less painful.
FAQ
Does 24% execution feasibility mean 24% of agent tasks work correctly?
No. Execution feasibility measures whether a workflow ran without syntax errors — not whether it returned the right answer. A plan can be perfectly executable and still call tools in the wrong order, pass incorrect arguments, or misinterpret results. Evoflux doesn't report task-success rate or answer quality. Your actual correct-answer rate is likely lower than 24%.
How many extra tokens does evolutionary search add per task?
Unknown. The Evoflux paper notes that ReAct carries "far higher variance and token cost" than zero-shot but doesn't quantify it (arXiv 2606.12674, 2026). Evolutionary repair's own overhead is also unmeasured. You need to count tokens across repair attempts on your workload to know whether the feasibility gain justifies the token cost.
Can I use evolutionary search and fine-tuning together?
Yes — and it may be the most effective approach for stable tasks with sufficient data. Use evolutionary search to discover successful execution trajectories, then fine-tune on those as training examples. Search addresses the data-scarcity problem that causes SFT to collapse; fine-tuning locks in the consistency that search alone can't guarantee. This hybrid is promising but understudied.
When does fine-tuning collapse below zero-shot?
On small, heterogeneous training corpora — which is the common starting point for teams building tool-calling agents. Evoflux shows SFT and SFT+DPO can perform worse than zero-shot under tight teacher-trace budgets (arXiv 2606.12674, 2026). The precise threshold isn't defined in the paper, but the pattern is consistent with what Fireworks AI observes across customers: fine-tuning without a strong eval harness and clean, domain-specific data routinely disappoints (Fireworks AI practitioner analysis, 2025).