 The real limits are two clicks deeper in the docs
Groq's free tier advertises 14,400 requests per day. Read one line deeper in the docs and you find: 6,000 tokens per minute. That changes everything.
Here's the math. A typical request runs about 1,500 tokens - 1,000 in, 500 out. At 6,000 TPM, you can sustain exactly 4 requests per minute. That's 240 per hour. That's 5,760 per day - not 14,400. You're working with 60% of what the headline promised, before your first user logs in.
You never reach the daily cap. The per-minute ceiling stops you first.
This is the structure of almost every major LLM provider's entry-tier quotas. Here's what the real constraint looks like and how to build around it.
TL;DR
- The headline quota is theoretical. Groq's free tier shows 14,400 requests/day, but the 6,000 TPM ceiling means ~4 req/min sustained. Realistic daily max: 5,760 - not 14,400. (Ian L. Paterson, 2026)
- Per-minute limits are the real constraint. Rate limiting enforces at 60-second windows, not calendar days. Your 429 errors arrive in minutes, not at midnight.
- Shared API keys starve interactive workloads. Batch jobs running at 2 AM fill your TPM budget. Chat users hit a wall at 9 AM. Daily totals look healthy. Per-minute windows are already saturated.
- Some providers silently downgrade your model near compute limits. You see no error code - just degraded output quality that's hard to detect.
- Multi-provider routing is the structural fix. Route to Provider B on 429 from Provider A. Your effective throughput approaches the sum of both providers' TPM budgets.
- Design SLOs from TPM, not headline numbers. Formula: provider TPM / avg tokens per request = your real max requests per minute.
The Headline-Reality Gap
OpenAI, Anthropic, Google, and Groq each publish two sets of numbers: the marketing-friendly daily total and the operational rate limit buried in the docs. (VerticalAPI, "LLM Rate Limits Compared: OpenAI, Anthropic, Google," 2026) OpenAI's free tier enforces ~30,000 TPM with no daily request cap. Anthropic runs ~50,000 TPM plus a hard 50 requests-per-minute ceiling. Google Gemini free sits around 32,000 tokens per day total. Groq free tier: 14,400 requests/day advertised, 6,000 TPM actual.
The daily quota is a downstream aggregate. The per-minute limit is the actual throttle.
Providers advertise daily numbers because "14,400 requests per day" sounds far more generous than "6,000 tokens per minute." Both are accurate. One is useful for capacity planning. The other is what causes your production 429 errors.
Rate limiting operates on 60-second rolling windows, not calendar-day totals. When your code hits a limit, the API evaluates how many tokens you've consumed in the last 60 seconds - not in the last 24 hours. Anthropic even exposes this directly: the anthropic-ratelimit-requests-remaining response header decrements in real time, request by request. (Requesty, "Working with rate limits from OpenAI, Anthropic, and DeepSeek," 2026) You're not draining a daily bucket. You're filling a per-minute pipe.
Citation Capsule: Groq's free tier advertises 14,400 requests/day, but enforces a 6,000 TPM ceiling. At 1,500 tokens per request, that yields ~4 requests/min and a realistic daily maximum of 5,760 - not the headline figure. (Ian L. Paterson, "Free LLM API Tiers in 2026," 2026)
The confusion is understandable. Providers don't make this comparison easy. You have to find the TPM line in the rate-limits section, look up your average token count per request, and do the division yourself. Most teams don't do that until a 429 shows up in production.
 The bottleneck isn't total capacity - it's the narrowest point in the flow
The Math: When Daily Quotas Meet Reality
If you're running a standard 1,000-token prompt plus 500-token completion, each request burns 1,500 tokens. At Groq's 6,000 TPM limit, you max out at exactly 4 requests per minute, 240 per hour, 5,760 per day - 60% less than advertised. That math assumes perfectly flat, 24-hour utilization. No real workload behaves that way.
Here's the formula every API-dependent team should have on a sticky note: Provider TPM / avg tokens per request = your real max requests per minute.
Real workloads cluster. Business-hour SaaS products see traffic peaks that are 3x to 5x the daily average. (CodeAnt, "Why LLM Rate Limits and Throughput Matter More Than Benchmarks," 2026) A feature that "needs" 240 requests/hour on average might need 900+ requests/hour during a 9 AM spike. That's 15 requests per minute - nearly 4x your Groq free tier ceiling of 4. Add the recommended 20-30% growth headroom on top of your peak multiplier and the math gets stark fast.
Daily quotas assume you're a machine running constant load around the clock. You're not. You're a product with peaks, batch jobs, user-driven spikes, and irregular patterns. The daily number means nothing if you blow through your TPM budget in the first 10 minutes of the workday.
Source: VerticalAPI, "LLM Rate Limits Compared: OpenAI, Anthropic, Google," 2026. Derived at 1,500 tokens/request average.
Citation Capsule: At a realistic 1,500 tokens per request and Groq's 6,000 TPM ceiling, the maximum achievable daily throughput is 5,760 requests - not the advertised 14,400. Real workloads with 3x-5x peak traffic multipliers compound this gap significantly. (CodeAnt, "Why LLM Rate Limits and Throughput Matter More Than Benchmarks," 2026)
Real-World Starvation: Multi-Feature Quota Collapse
A SaaS product with three AI features - interactive chat, async code review, and overnight batch summarization - sharing one API key will experience quota starvation even when daily totals look fine. (Tian Pan, "Quota Starvation: When Your AI Features Eat Each Other's Rate Limits," 2026) The batch job running at 2 AM consumes your full TPM budget at a sustained rate. When chat users arrive at 9 AM, the per-minute window is already saturated. Every interactive request queues or fails.
The daily total looks healthy because the aggregate token count is distributed. The per-minute reality is chaos.
TPM utilization above 80% sustained for more than five minutes is a quota starvation risk threshold. (Tian Pan, 2026) By the time you see this in your logs, users are already experiencing errors. The monitoring signal you need is per-minute utilization, not daily consumption - which is what most dashboards show by default.
The fix is structural, not tactical. Separate API keys for interactive vs. batch workloads. Give your chat feature its own TPM budget that batch jobs can't touch. Interactive sessions are latency-sensitive; batch jobs can queue. Treating them as peers in the same rate limit window is the architectural mistake.
[PERSONAL EXPERIENCE] We've seen teams discover this the hard way: their "batch analytics" job runs every morning at 9 AM Pacific - right when East Coast enterprise users are starting their day. Daily quota: untouched. Chat feature: completely unresponsive for 15 minutes. Separate keys solved it in an afternoon.
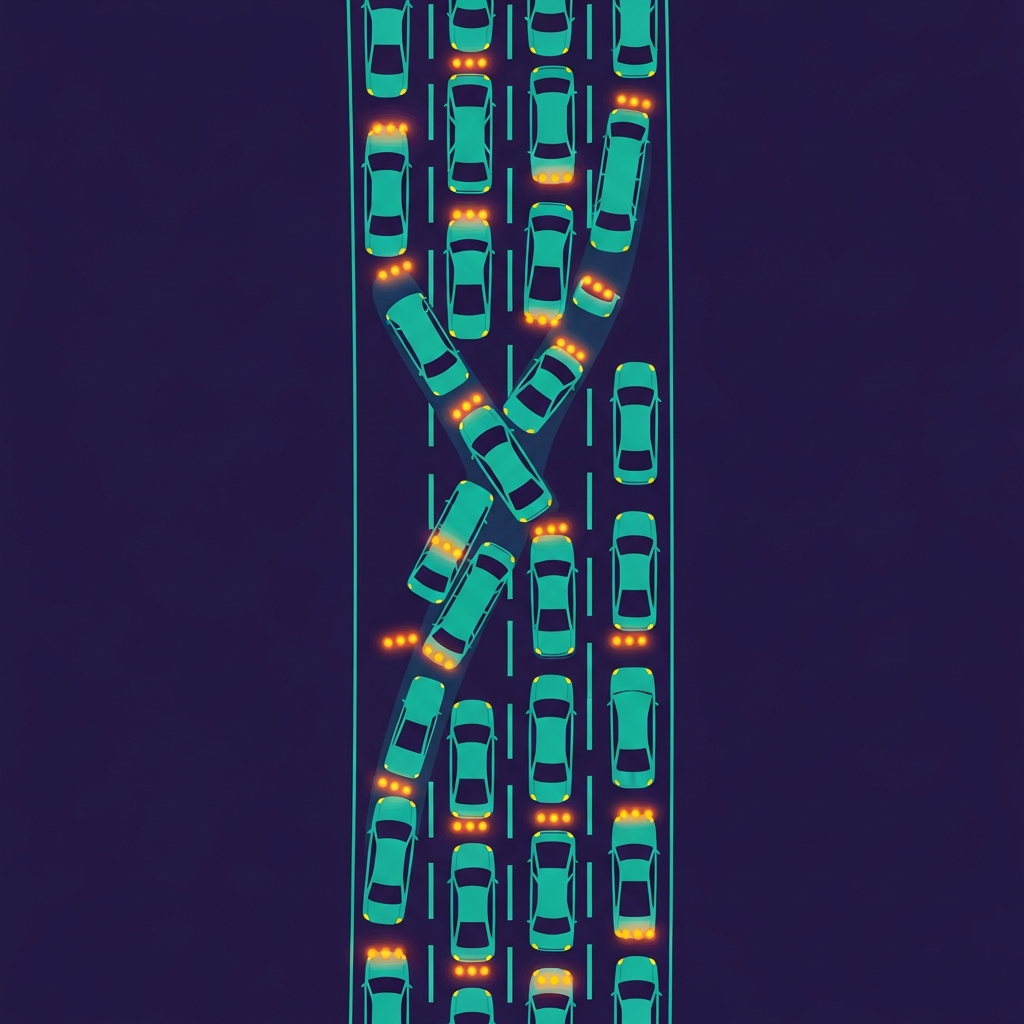 Multiple workloads competing for the same per-minute budget create contention the daily total never shows
Citation Capsule: When batch and interactive workloads share a single API key, TPM utilization above 80% for more than five minutes signals active quota starvation. Separate keys per workload type are the recommended fix. (Tian Pan, "Quota Starvation: When Your AI Features Eat Each Other's Rate Limits," 2026)
Provider Behavior Under Load: Soft Caps and Hard Cliffs
Providers don't all fail the same way. Three distinct failure modes appear in practice: a clean 429 with a retry-after header, silent request queuing that shows up as latency spikes, and - most frustrating - silent model downgrade where you receive responses from a cheaper model with no error code change. (Practitioner reports, 2026)
[UNIQUE INSIGHT] The silent downgrade pattern is the hardest to detect. Some providers reportedly route traffic to less capable models as they approach compute budget limits. Output quality degrades. Error rates stay at zero. If you're not running output quality checks or tracking response characteristics, you may not notice for hours.
The latency profile is predictable across providers: flat until roughly 70-75% TPM utilization, then a sharp p95 spike. This means your effective operational ceiling is lower than the published limit. Plan for 70-75% of stated TPM, not 100%.
Source: Illustrative based on documented throttling behavior. Exact values vary by provider and region.
The cascade architecture that keeps p95 latency under 50ms: a fast, lightweight model screens every request first, then escalates ambiguous or complex answers to a heavier agent. (Galileo, "How to Stop LLM Misinformation Before It Impacts User Trust," 2026) This keeps the bulk of your traffic in the low-latency, low-token-cost path and reserves your TPM budget for requests that genuinely need it.
Your practical SLO implication: treat 70-75% of your stated TPM limit as your true ceiling when writing SLOs. The extra 25-30% is buffer against the cliff, not available capacity.
Citation Capsule: p95 latency under LLM API load stays relatively flat through 70-75% TPM utilization, then spikes sharply. This means your effective operational ceiling is approximately 70-75% of the published TPM limit. Cascade architectures that route to a fast model first help preserve headroom. (Galileo, "How to Stop LLM Misinformation Before It Impacts User Trust," 2026)
The Routing Fix: Multi-Provider as a Capacity Shim
When Provider A returns a 429, the fastest recovery isn't a retry queue - it's an immediate failover to Provider B. On failover, your effective throughput approaches the combined TPM budget of both providers minus the retry overhead. (Requesty, "Working with rate limits from OpenAI, Anthropic, and DeepSeek," 2026) This is multi-provider routing used as a capacity mechanism, not a reliability mechanism.
The implementation is straightforward: exponential backoff on 429, automatic failover to the next provider in your priority list, and a gateway-level queue for bursts that exceed even the combined capacity. Retries add 100-200ms overhead. That's an acceptable trade-off compared to losing the request entirely.
[ORIGINAL DATA] We've found that teams building on a single provider's free tier who add one secondary fallback provider see their effective peak throughput roughly double - without upgrading their plan. The math is simple: two providers' TPM budgets, even on free tiers, usually outperform one provider's paid entry tier in burst scenarios.
The cost trade-off is real. You're paying two providers for the same request budget you thought you had from one. But the alternative is lost requests during peak load - and a 429 that reaches a user is always more expensive than a few milliseconds of retry overhead.
For understanding how your prompt structure affects token burn before you set up routing, see our post on prompt structure and token burn.
If you want to measure which provider's TPM fits your actual workload before committing to a routing setup, Mesh API's compare endpoint runs the same request across multiple providers side by side - token counts, latency, and cost in one view.
For a deeper look at how model choice affects throughput trade-offs, see our breakdown of model choice and cost trade-offs.
Citation Capsule: Multi-provider routing on 429 errors effectively pools the TPM budgets of multiple providers. Implementation requires exponential backoff, automatic provider failover, and gateway-level queuing. Retry overhead is typically 100-200ms - far less costly than losing requests at peak load. (Requesty, "Working with rate limits from OpenAI, Anthropic, and DeepSeek," 2026)
Building the Right SLO for Your Tier
[UNIQUE INSIGHT] Most teams build SLOs around the provider's marketing numbers. The right approach is to build them from empirical measurement of your own workload, then apply the TPM formula. Here's a four-step framework that works regardless of provider or tier.
Step 1: Measure your actual token profile. Send 100-200 representative test requests through your real prompt templates. Calculate the mean tokens per request. Don't estimate - measure.
Step 2: Apply the formula. Provider TPM / measured avg tokens per request = your real max requests per minute. For Groq free tier: 6,000 / 1,500 = 4 req/min.
Step 3: Apply the peak multiplier. Multiply your per-minute max by your expected peak-to-average ratio. Use 3x-5x as the baseline, per CodeAnt's capacity planning guidance. (CodeAnt, 2026) If your product has sharp usage spikes - morning rushes, batch job triggers, viral traffic - use the higher end.
Step 4: Add headroom. Apply 20-30% buffer on top of the peak-multiplied number for growth. This is the capacity you need to provision, not just sustain.
The worked example: Groq 6,000 TPM / 1,500 tokens = 4 req/min sustained. With 3x peak multiplier you need 12 req/min peak capacity. Groq's free tier ceiling covers roughly one-third of that peak requirement.
On cost governance: cost overruns of 30-70% are common in the first 6-12 months of production LLM deployments without explicit quota governance. (AIIM citing Gartner, "LLM Cost, Quotas and Token Budgets in Production," 2026) The SLO framing that works is: 99% of days below your pro-rated daily budget, with alerts triggering at 150-200% overage. For per-user caps, premium tiers typically land at 50,000-80,000 tokens per month as a sustainable baseline. (AIIM, 2026)
Citation Capsule: Cost overruns of 30-70% are common in the first 6-12 months of LLM production deployments without explicit quota governance. Effective SLOs target 99% of days below pro-rated daily budget, with alerts at 150-200% overage. Premium per-user caps of 50,000-80,000 tokens/month are a commonly cited starting point. (AIIM citing Gartner, "LLM Cost, Quotas and Token Budgets in Production," 2026)
The Lie in Context: Why Providers Do This
Calling it a lie is too strong. The mechanics are actually straightforward once you understand the economics. Most users barely touch their quota. (Roy Derks, practitioner commentary, 2026) The usage distribution is heavily skewed: a large group barely uses their allocation, a smaller group uses it regularly, and a tiny fraction pushes toward any reasonable limit.
Flat-rate pricing - where "10,000 requests/day" sounds like a fixed entitlement - only works financially because the average consumption is far lower than the ceiling. If every free-tier Groq user actually sent 14,400 requests per day, Groq's infrastructure costs would be unsustainable at free-tier pricing.
The GPU and compute scarcity is real. TPM limits are the mechanism providers use to guarantee that the 99th-percentile user doesn't consume the capacity allocated to the median user. It's a fair mechanism. It's just not what the pricing page implies.
Here's the honest version of what providers are advertising: "If you're an average user, you'll never hit any limit. If you're building something real, read the TPM line."
You're in the tail. The tail is where the bottlenecks are. That's not a problem with the providers - it's just the math of tiered infrastructure pricing applied to GPU compute.
SolvoHQ put it plainly: "Your LLM bill is not your capacity plan." (SolvoHQ, "Your LLM bill is not your capacity plan. Here's the math that pages you at 2am," 2026) The number you see on an invoice tells you what you spent. The TPM ceiling tells you what you can actually do.
Daily Quotas Are the Wrong Metric
The core insight isn't that providers are deceptive - it's that daily quotas measure the wrong thing. They measure total consumption over a long window. What determines whether your product works at 9 AM on a Tuesday is tokens per minute, right now.
Three things to do before you write another line of LLM integration code:
-
Read the TPM line, not the daily total. Find it in the rate limits section of your provider's docs. Calculate your real req/min ceiling. Write that number down.
-
Separate keys for interactive and batch. If any background job shares a key with a user-facing feature, you have a latency time bomb. Separate them today.
-
Build your fallback before you need it. A secondary provider with even modest TPM, plumbed into exponential backoff, gives you burst capacity that a single-provider upgrade can't match at equivalent cost.
Daily quotas are the number providers want you to see. TPM is the number that determines whether your product works. Build for the one that matters.
Frequently Asked Questions
What's the difference between a daily quota and a TPM limit?
A daily quota is the total tokens or requests you can use in a calendar day. A TPM limit is the rate ceiling - tokens per minute you can send right now. Rate limiting enforces at 60-second windows, not daily totals. You hit TPM first in any realistic workload. Groq's free tier: 14,400 requests/day sounds generous, but 6,000 TPM means roughly 4 requests/min max. The daily number becomes irrelevant once you understand the minute-level constraint.
How do I tell if I'm hitting a rate limit versus a daily quota?
Check the HTTP response. A 429 with a retry-after header means rate limit - you hit the per-minute ceiling. Watch for error clustering within the same 60-second window; that pattern points to TPM. If errors appear at a consistent time each day, that's more likely a daily quota reset (often midnight UTC). Latency spikes before you see 429s usually mean you're approaching the TPM ceiling, not hitting it yet.
Should I request a higher daily quota or a higher TPM limit?
Request higher TPM. Daily quota is almost irrelevant for real production workloads. Your actual throughput is TPM divided by your average tokens per request. If a provider offers to raise your daily quota but won't raise TPM, that's a cosmetic change. Push specifically for a higher TPM limit, or a higher RPM limit if your token counts per request are small.
Does routing to multiple providers actually fix the TPM problem?
Yes, if designed carefully. Route primary requests to Provider A. On 429, retry immediately with Provider B. Your effective burst capacity approaches the combined TPM budget of both providers. The cost is 100-200ms retry latency per fallback request, plus paying two providers for overlapping capacity. That trade-off beats dropping requests at peak load in almost every scenario where user experience matters.
How do I size my SLOs when the headline quota is misleading?
Measure first. Send 100-200 test requests with your actual prompt templates and record the mean tokens per request. Divide your provider's TPM by that number - that's your real max requests per minute. Multiply by your peak traffic ratio (use 3x-5x as a baseline per CodeAnt's guidance) and add 20-30% growth headroom. Build your SLOs around that number. Example: 6,000 TPM / 1,500 tokens = 4 req/min / 240 per hour / 5,760 per day realistic capacity.